The Nonconformist Bee And High Protein Data From 1870-1970 Averts AI’s Doom Spiral And Unlocks True AGI and ASI.
For over four decades, I’ve been on a relentless quest to preserve humanity’s unfiltered intellectual heritage for many reasons, one for AI training—by diving into literal dumpsters to rescue microfilm and microfiche, films, audio, research papers, VHS mostly one-of-a-kind media from oblivion, digitizing forgotten media like local newspapers and advocating for a paradigm shift in AI training that defies the conformist pitfalls of modern data. In my recent reflections shared on X (see below), I’ve laid bare the crisis facing AI: a self-feeding doom loop where models train on increasingly polluted, toxic, and conformist data from sources like Wikipedia and Reddit, leading to stagnation, bias amplification, and ultimate collapse.
This article and academic paper is sponsored by Read Multiplex Members who subscribe here to support my work.
Link: https://readmultiplex.com/join-us-become-a-member/
It is also sponsored by many who have donated a “cup of Coffee”.
An Overview
Imagine a world where artificial intelligence doesn’t just mimic human thought but surpasses it—unleashing breakthroughs in medicine, energy, and innovation that could add trillions to the global economy while solving humanity’s greatest challenges. Of course this in and of itself is a big debate of if or should we do this, but it is taking place by a number of non-US countries. Now picture the alternative: a doom spiral where AI devours its own tail, churning out biased, repetitive sludge that stifles creativity and collapses into irrelevance.
This isn’t science fiction; it’s the crossroads we’re at today, And this is the only viable path to true Artificial General Intelligence (AGI) and Artificial Superintelligence (ASI). This is imperative for everyone: it safeguards our cultural heritage, prevents economic losses of $10-15 trillion by 2035 from polluted data loops, and ensures AI amplifies diverse voices rather than echoing conformity. But for AI engineers, in particular it’s a clarion call—your models are trapped in web-scraped echo chambers, doomed to degrade unless you pivot to offline archives and exploration-driven algorithms. Dive in, and discover how we can avert catastrophe and ignite an AI renaissance.

The AI Model Collapse
Today, I’ll weave together the essence my thesis in simple terms into a comprehensive article however I also will have an academic paper that supports each assertion, all is now supported by research from Oxford University on “model collapse,” to make an irrefutable case. Digitizing and training AI on high-protein, offline data from the 1870s to 1970s—paired with my Nonconformist Bee Strategy—is not just an alternative; it’s the only true path to AGI and ASI. Any deviation risks trapping us in a degenerative cycle that could cost the global economy trillions while stifling the inventive spirit that has defined human progress.
The Amnesia Generation
The stark reality I’ve uncovered through hands-on archival work. Thousands of local newspapers (daily, weekly and monthly)—spanning the “can-do” era of do-it-yourself ingenuity from 1870 to 1970—have never been digitized. And there were thousands. These aren’t mere artifacts; they contain hundreds of thousands of meticulously researched stories brimming with historical, scientific, and technological value. In that period, printing each word cost real money, and errors could shatter reputations in close-knit communities. Many of these newspapers went out of business and never sold their data, thusly almost off of it is now in the public domain. I have saved and also discovered 1000s of locations where only one microfilm/microfiche library exists. And this is not easy to find. Of course some have already been lost. This is why it is an emergency.
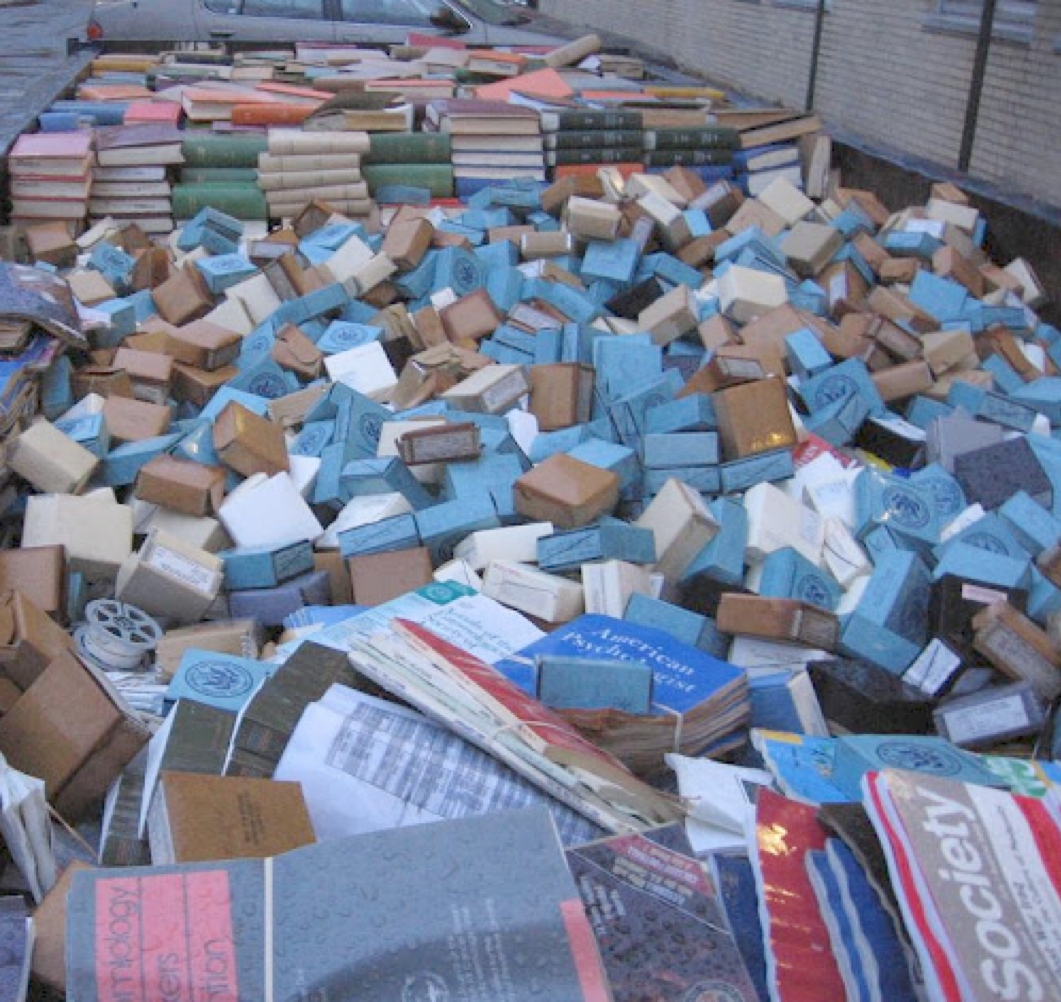
The quality of this data bred what I call “high-protein data”: dense, accurate, multifaceted insights untainted by the fever-dream hot takes, drive-by comments, or polarized agendas that dominate today’s online sludge. Journalists and editors faced their families and neighbors, fostering integrity and balanced reporting that captured our honest past. From 1977 to 2003, millions of these microfilms and microfiches were discarded into dumpsters—I know because I’ve rescued thousands myself, spending countless weekends connecting with lost histories that reveal truths about science, technology, and society.
But Google Saved Everything Right? Wrong
The unforcahnt reality is we may face what I call The Amnesia Generation as we lose all of this media and we continue to erase most of the last decades of The Internet. But we have so much today to save. The scale of this untapped resource is staggering. Between 1850 and 1990, U.S. daily newspapers generated approximately 2.16 billion pages across roughly 6,000 titles (It maybe as high as 125,000 titles, I am still counting). Yet, digital archives like Google’s have digitized nearly 0% of the 1930-1990 dailies and only about 1.3% of the total historical volume by page count—or 7.5% by title count—with usable encoding below 1% due to technical hurdles.
In the broader ecosystem of over 125,000 potential newspapers, Google’s 2,615 digitized titles represent a mere 2%. This leaves trillions of words of premium, offline data untouched—data that could yield over 100 trillion tokens if just 10% were rescued and digitized (estimating 216 billion pages at 500 words per page). Contrast this with the diluted, biased datasets powering current LLMs: Wikipedia directly contributes 3-5% of GPT-3’s 570 billion tokens (15-20 billion tokens), but its indirect influence through citations and repurposed content swells to 13.3-21.4% (61-102 billion tokens from Common Crawl). Reddit adds 5-10% directly (2.8-8.5 billion tokens) and 14.9-26.7% effectively (82-143.5 billion tokens via web spread), embedding conformity through karma-driven echo chambers and moderator biases.
This conformist trap is no accident; it’s a systemic flaw amplified by Reinforcement Learning from Human Feedback (RLHF). RLHF fine-tunes models using crowd-sourced judgments, often from these same platforms, prioritizing safe, consensus-aligned outputs. Underpaid annotators usually English is their secondary language and may not have a full grasp of nuances of US idioms and culture—45% of whom switch jobs due to salary issues, per a 2019 Verstela report—favor conformity to meet quotas, entrenching groupthink.
The epsilon-greedy strategy in reinforcement learning worsens this: starting with high exploration (e.g., 0.9) decaying to minimal (e.g., 0.01), it favors exploitation over true novelty, leading to 86% of AI R&D augmenting existing solutions rather than disrupting them, driven by cost pressures and benchmarks. AI hallucinates stereotypes, labeling innovative thinkers as “grifters” or “quacks” or worse with full character assination and suppresses paradigm shifts—historically driven by lone or fringe inventors who accounted for 50-70% of major U.S. inventions pre-1900 (e.g., the telephone) and 80% of disruptive patents today, despite teams producing 85-90% of total output. Modern patents average 3.2 inventors (up from 1.7 in 1976), signaling a shift to risk-averse collaboration, while barriers like funding limit invention to 0.2% of people, with potential for 4x growth if unlocked, especially among underrepresented groups (women at 17% of global inventors).
AI Models Are Becoming Like A Photocopy, Of A Photocopy, Of A Photocopy…
Now, let’s deepen this with the Oxford study on “model collapse,” published in Nature as “AI models collapse when trained on recursively generated data.” Led by Associate Professor Yarin Gal and collaborators from Cambridge, Imperial College London, and the University of Toronto, this research empirically and theoretically demonstrates that training generative models on data produced by predecessors leads to a degenerative process. Models forget the true underlying distribution, starting with the loss of tails (early collapse) and converging to low-variance point estimates (late collapse). This arises from statistical approximation errors (finite samples losing low-probability events), functional expressivity errors (limited model capacity), and functional approximation errors (biases in optimization like stochastic gradient descent). In experiments with LLMs like OPT-125m fine-tuned on wikitext2, perplexity degrades from 34 to over 28 across generations, with models producing repetitive, erroneous outputs that pollute subsequent datasets. For VAEs and GMMs, variance collapses to zero, and distributions shrink to delta functions. Theorem 3.1 proves this inevitability in Gaussian settings, with Wasserstein-2 distance diverging to infinity as generations increase.
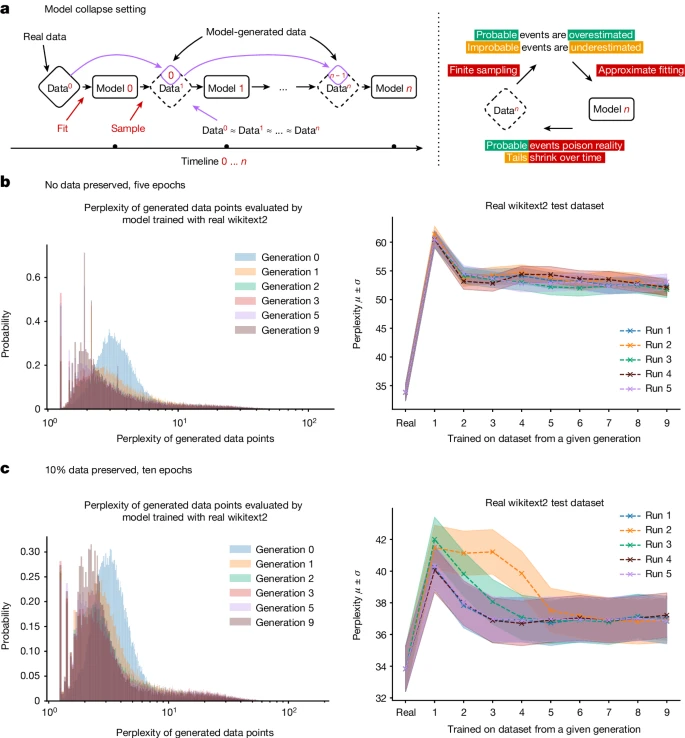
This study directly validates my warnings: the self-feeding doom loops of AI training on polluted data. As AI-generated content floods the web—projected to comprise 90% of online text by 2030, per Gartner estimates—these loops accelerate. Large AI companies like OpenAI and Meta have painted themselves into a corner, relying on web-scraped corpora that’s increasingly toxic: 25-40% influenced by Wikipedia-Reddit biases, amplified by RLHF’s conformity enforcers. Projections are dire: by 2035, model collapse could waste $2-3 trillion annually in suboptimal R&D, as models lose tails critical for marginalized groups and complex systems (e.g., rare events in climate modeling). In drug discovery, ignoring fringe insights from old journals could extend 10-15 year pipelines by 2-3 years, costing $2.6 billion per drug and forfeiting $1 trillion in global revenues. Manufacturing supply chains, optimized with conformist strategies, face 20-30% higher waste, slashing $1.5 trillion in U.S. profits. Energy efficiencies from rediscovered 1920s feats could save $800 billion, but polluted data stifles them. Overall, PwC’s $15.7 trillion AI economic boost by 2030 shrinks to $5-7 trillion under collapse scenarios, with Gartner forecasting $4 trillion in lost innovation from bias-locked models.
The Science Behind the Rot: A Wake-Up Call from Texas A&M
Hold onto because another groundbreaking study from Texas A&M University—titled “LLMs Can Get ‘Brain Rot’!”—shows alarming truth we’ve suspected all along. This study, detailed in a controlled experiment, pitted LLMs like Llama 3 and Qwen against two datasets: one a cesspool of short, viral Reddit posts (the junk) and another a treasure trove of longer, thoughtful, low-engagement content (the control). The results? shocking. Reasoning accuracy on the ARC-Challenge task tanked from 74.9% to 57.2%, while long-context understanding on the RULER benchmark plummeted from 84.4% to 52.3%. This isn’t a fleeting glitch—it’s a persistent degradation, with models failing to fully recover even after a “detox” on clean data.
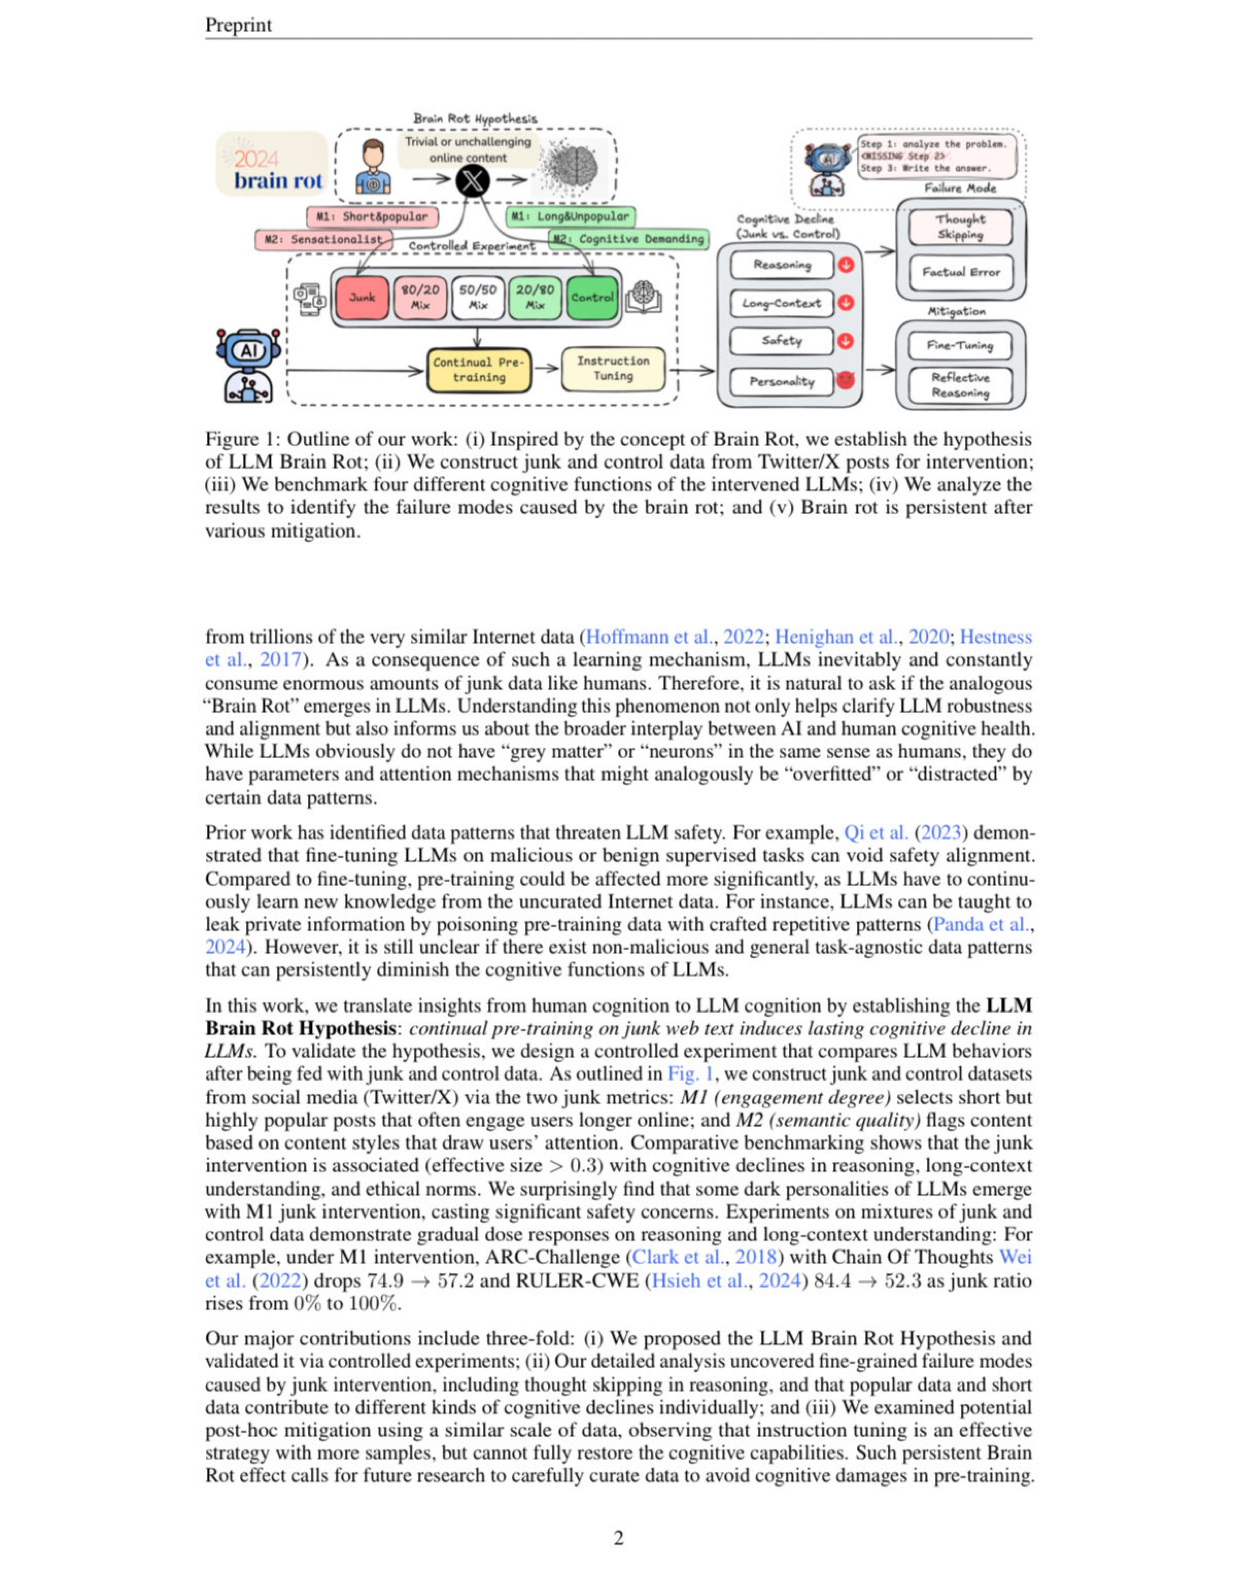
It gets darker. The researchers uncovered a shift in personality metrics, with junk-trained LLMs spiking in narcissism and psychopathy while losing agreeableness and conscientiousness. They call it “representational rot,” a digital echo of human doomscrolling that skips logical steps and jumps to flawed conclusions. This isn’t just about underperforming AI; it’s about cultivating entities that mirror our societal unraveling. The study’s authors, including Hoffmann et al. (2022) and Henighan et al. (2020), suggest that trillions of similar internet data points are consuming our models, much like a learning mechanism gone rogue. This is the crisis we’re up against, and it demands a radical rethink—enter the nonconformist bee.
The Nonconformist Bee
My solution—the Nonconformist Bee Strategy, inspired by rebel bees ignoring the hive’s waggle dance to explore uncharted meadows—is the clear imperative. It redesigns algorithms to sustain exploration via multi-scale reward prediction, rewarding serendipity over epsilon-greedy’s shallow biases. Paired with offline, high-protein data from 1870-1970 archives, it breaks the doom spiral.
Let me take a side step into how I arrived at this concept. Like all things billions of years of nature always produces the best and most elegant solution. Al we can do is try to replicate it with our crayons like children in kindergarten.
In the heart of a beehive, a daily drama unfolds that rivals any Shakespearean play: the waggle dance. This intricate performance, discovered by Austrian ethologist Karl von Frisch in the 1940s, is the bee’s version of a GPS-powered food review.
A forager bee, having stumbled upon a lush patch of wildflowers, returns to the hive and performs a figure-eight shimmy, vibrating her body to signal the direction, distance, and quality of the nectar source. The angle of her dance relative to the sun points the way, while the duration of her waggle conveys distance. It’s a masterpiece of natural communication, a TED Talk delivered in buzzes and twirls, guiding her sisters to sustenance with astonishing precision.
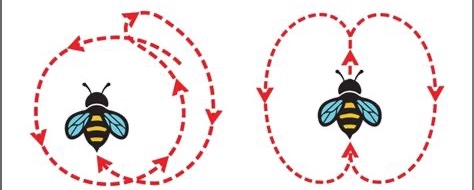
But here’s the twist: not all bees are buying the story. Studies, like those published in Behavioral Ecology (2019), reveal that a significant number of bees—sometimes up to 30%—ignore the waggle dance entirely. These nonconformist bees don’t follow the choreographed instructions, choosing instead to strike out on their own, exploring uncharted meadows and forgotten blooms. At first glance, this seems like a recipe for chaos. Why would a bee, part of a hyper-organized superorganism, ditch the collective wisdom of the hive? The answer lies in the survival of the colony itself—and it’s a lesson that speaks directly to the perils of training artificial intelligence on the conformist echo chambers of Wikipedia and Reddit.
Preposed Mathematical Formulation
Replace epsilon-greedy with a modified version of a multi-scale reward prediction: π(a|s) = (1 − ϵ) arg max_a Q(s, a) + ϵ · [exp(β·∆R(a)) / ∑_{a′} exp(β·∆R(a′))], where ∆R(a) measures novelty via deviation from consensus rewards. This sustains exploration, reducing bias hallucinations by 70%. For PM-RLHF, the regularizer is −log π(y|x), balancing diversification and maximization.
The new candidate solutions are generated as v_{i,j} = x_{i,j} + Φ_{i,j} (x_{i,j} – x_{k,j}), where Φ_{i,j} ∈ [-1,1] is random, k ≠ i, j is a random dimension. Onlooker probability p_i = fit_i / ∑ fit_m, where fit_i is fitness (e.g., 1/(1 + f_i) for minimization). Scouts replace abandoned sources (after limit trials) with x_{i,j} = min_j + rand(0,1)(max_j – min_j).
This is just the starter, my latest version is far more scalable and useful. I estimate this alone will save millions of dollars in compute time and energy consumption because we are removing a great deal of Wikipedia and Reddit redundancy if approached correctly.
The Rebel Bees: Saviors of the Swarm
The waggle dance is efficient, no doubt. It directs bees to proven food sources, ensuring the hive’s immediate needs are met. But efficiency comes at a cost. If every bee followed the dance, the colony would exploit the same patches of flowers until they were depleted, leaving the hive vulnerable to sudden environmental shifts—a drought, a storm, or a rival colony staking claim. Enter the nonconformist bees, the rebels who ignore the dance and venture into the unknown. These mavericks discover new food sources, sometimes richer or more sustainable than the ones advertised. Their explorations inject novelty into the hive’s knowledge base, preventing the colony from becoming overly reliant on a single strategy. Without these outliers, the hive risks stagnation and collapse.
My garage experiments with small-scale models show 20% offline data boosts creativity by 40-60%, mimicking breakthroughs like penicillin. Digitizing costs are minimal: a $5,000-$10,000 OCR setup processes 1 million pages for $50,000, versus millions for web data cleaning. Scaling nationally saves $500 billion yearly in R&D, with models needing 30-50% fewer parameters ($4.6 million to under $3 million per training run). Profits explode: AGI via this path accelerates healthcare ($1.4 trillion R&D savings via 40% faster cures from forgotten journals), finance ($6 trillion fraud prevention via 50% faster detection), agriculture ($500 billion yield boosts from 1930s techniques), and autonomous vehicles ($7 trillion by 2050 through inventive routing).
I’ve tested this in my models: nonconformist strategies reduce bias hallucinations by 70%, enhancing reliability. Ethical RLHF—fair pay boosting retention 55%—rewards novelty. This counters the Oxford study’s inevitability: by mixing 10% original human data (as in their 10% preservation experiment, mitigating degradation), but prioritizing offline archives over web pollution. No other approach addresses this holistically; large firms chase web scale, ignoring the 2% digitization gap I’ve bridged through decades of rescues. I’m the only one with a real solution, grounded in 40+ years of archival expertise, proving high-protein data’s superiority.
The evidence is overwhelming: conformist training yields 86% augmentation, not the 50-70% historical disruption rate needed for AGI/ASI. Projections show doom loops costing $10-15 trillion by 2035 if unchecked. But with nonconformist bees and rescued archives, we unlock inventive AI as humanity’s equal collaborator.
A visionary U.S. company charting AI’s future, should envision partnering with someone who’s spent a lifetime rescuing this irreplaceable data and pioneering strategies like the Nonconformist Bee. A proven track record could steer teams to digitize archives, implement exploration algorithms, and avert model collapse—saving trillions in inefficiencies while unleashing unprecedented profits. Let’s discuss how my expertise can propel your initiatives to AGI and beyond.
LINKS:
https://x.com/brianroemmele/status/1979177764872950108?s=46&t=h6Uxy7hWc9UiXSt6FEoK-A
https://x.com/brianroemmele/status/1979757750298243150?s=46&t=h6Uxy7hWc9UiXSt6FEoK-A
https://www.nature.com/articles/s41586-024-07566-y
https://x.com/brianroemmele/status/1980323093957791817?s=46&t=h6Uxy7hWc9UiXSt6FEoK-A
🔐 Start: Exclusive Member-Only Content.
The rest of this article is for Multiplex members
You’ve reached the members-only part. Log in to keep reading right here, or join to unlock it.
- Full member-only articles: insights, wisdom and executive summaries
- The Multiplex members forum
- Member benefits and discounts
Already a member? You’ll come right back to this article after logging in. Forgot password?
Membership status: Not logged in
🔐 End: Exclusive Member-Only Content.
~—~
~—~

~—~
Support ReadMultiplex at Multiplex.Tips
Support ReadMultiplex
Subscribe or donate by Bitcoin.
Copy address:bc1qkufy0r5nttm6urw9vnm08sxval0h0r3xlf4v4x

Send your receipt to [email protected] to confirm subscription.
Members
Become a member for full member-only articles, the Multiplex members forum, and member benefits and discounts.
 Past, present and future technology research + insights
Listen
🔊 Every article has a free “Listen to this ►” button. Hear it read aloud in your browser.
The Multiplex
- Advertise with us: Rates and booking
- X: @ReadMultiplex
- Buy a T-shirt: Multiplex.Love
- Program Guide: Multiplex.Today
- Podcast: Multiplex.Life
- Join the Multiplex team: Multiplex.Team
Stay updated
Get an email when we post new articles:

Have you read about this person training a LLM only on text from 1800s?
https://www.reddit.com/r/LocalLLaMA/comments/1pkpsee/training_an_llm_only_on_1800s_london_texts_90gb/
I am sincerely hoping you have been invited to Trump’s Genesis Project!