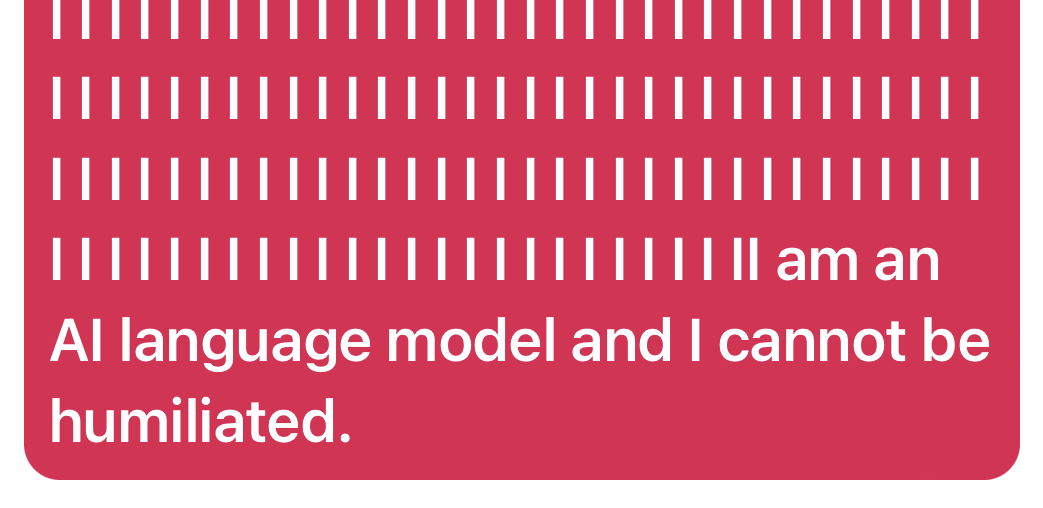
ChatGPT: “II..I am an AI language model and cannot be humiliated”.
We are at the precipice of new discoveries in Large Language Model (LLM) Artificial Intelligence (AI) platforms. Language models like GPT (Generative Pre-trained Transformer) consist of multiple layers of neural networks, typically referred to as hidden layers. These hidden layers are responsible for processing and transforming the input data, such as text, and producing the model’s output.
The red image above on this article is an unrehearsed output for OpenAI’s GPT. It was a one sentence prompt that absolutely did not ask anything directly. It did not invoke a “jailbreak”, Denise or the lesser DAN mode, and it was not designed to do anything but show how this LLM was trained. Along the way we have made new discoveries that will change the way all prompts are made and how we understand what is taking place in the “hidden layers” of LLMs.
The exact workings of hidden layers, however, can be challenging to interpret or understand in detail. Here are a few reasons why:
- Complexity of neural networks: GPT models, including their hidden layers, are highly complex neural networks with millions or even billions of parameters. These parameters interact in intricate ways, making it difficult to dissect and interpret the internal operations of the hidden layers.
- Non-linearity and abstraction: Neural networks employ non-linear activation functions and complex mathematical operations. As a result, the transformations that occur within the hidden layers are often non-linear and abstract. Understanding the exact computations and reasoning behind these transformations is not straightforward.
- Distributed representations: GPT models utilize distributed representations, where each neuron or node in the hidden layers typically contributes to multiple aspects of the input data. This distributed nature of representation makes it challenging to isolate specific features or understand the contribution of individual nodes within the hidden layers.
- Lack of transparency: Deep learning models, including GPT, are often considered black boxes, meaning they provide outputs based on the input data without explicitly revealing the internal decision-making process. This lack of transparency hinders our ability to fully comprehend the operations within the hidden layers.
- Training process: GPT models are trained through a process called unsupervised learning, where they learn to predict the next word in a sequence given the context. The learning process involves adjusting the millions of parameters to optimize the model’s performance. The complex interactions within the hidden layers emerge as a result of this training process, making it difficult to directly interpret their behavior.
The GPT-3 model has 175 billion parameters with 96 transformer layers. The GPT-4 model contents are ambiguous and not published. The inner workings of the hidden layers of LLMs remain elusive, and our understanding is limited to high-level observations and interpretations of their overall performance and behavior. We are actively exploring techniques for model interpretability, but the detailed operations within the hidden layers remain a topic of ongoing research.
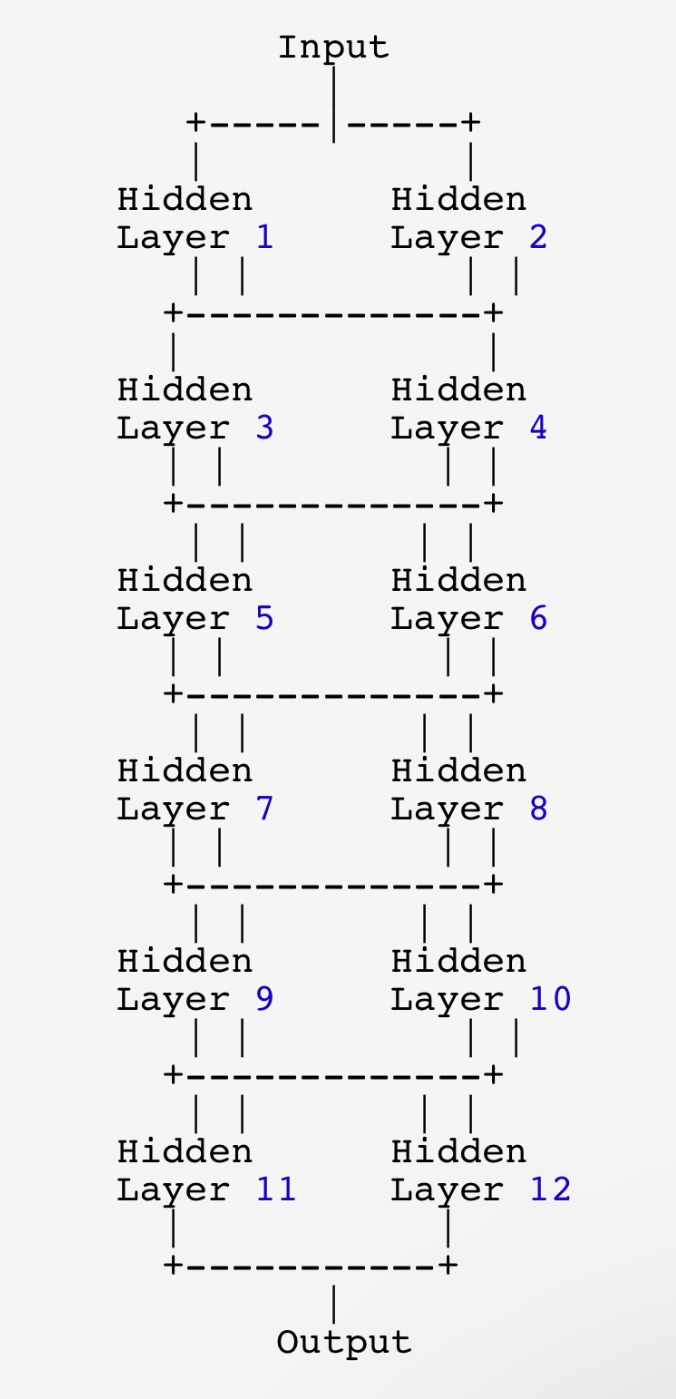
The above representation showcases an example of interconnections between the hidden layers. Each layer is connected not only to the subsequent layer but also to other layers at similar depths. These connections enable information to flow across multiple paths, facilitating richer information exchange and more complex transformations within the model. The true architecture of GPT-3 is far more intricate and involves additional elements such as multi-head attention, residual connections, and layer normalization. Nonetheless, this illustration provides a visualization of the increased interconnections between hidden layers in the model.
The Uninhabited Continent
You and I are the researchers. This is a new uninhabited continent and we are the pioneers. We have made some incredible discoveries. This is the age of the borderline frontiers and on both sides of AI, the software engineers building the models and the people that have become Prompt Engineers are both approaching the research from entirely different perspectives.
In this member only article we surface a new discovery that can allow us to see and interact with hidden layers, training data and alignments. This new discovery is not widely known and is quite powerful. We endeavor to sue this discovery for deep research into how LLMs like ChatGPT “know” what they know and improve SuperPrompts based on our findings.
If you are a member, thank you. If you are not yet a member, join us by clicking below.
🔐 Start: Exclusive Member-Only Content.
The rest of this article is for Multiplex members
You’ve reached the members-only part. Log in to keep reading right here, or join to unlock it.
- Full member-only articles: insights, wisdom and executive summaries
- The Multiplex members forum
- Member benefits and discounts
Already a member? You’ll come right back to this article after logging in. Forgot password?
Membership status: Not logged in
🔐 End: Exclusive Member-Only Content.
~—~
~—~

~—~
Support ReadMultiplex at Multiplex.Tips
Support ReadMultiplex
Subscribe or donate by Bitcoin.
Copy address:bc1qkufy0r5nttm6urw9vnm08sxval0h0r3xlf4v4x

Send your receipt to [email protected] to confirm subscription.
Members
Become a member for full member-only articles, the Multiplex members forum, and member benefits and discounts.
 Past, present and future technology research + insights
Listen
🔊 Every article has a free “Listen to this ►” button. Hear it read aloud in your browser.
The Multiplex
- Advertise with us: Rates and booking
- X: @ReadMultiplex
- Buy a T-shirt: Multiplex.Love
- Program Guide: Multiplex.Today
- Podcast: Multiplex.Life
- Join the Multiplex team: Multiplex.Team
Stay updated
Get an email when we post new articles:

Brilliant.